Smart Money Concepts arrived as a reaction to a real problem: classical technical analysis describes what price did, but it rarely tells you why a level mattered or what a large participant was likely doing when it broke. SMC — and the ICT framework it mostly descends from — tries to answer that by naming the mechanics underneath the chart. A sweep of resting stops. A gap left behind by an aggressive move. A zone where the last sellers handed off to buyers before the rally started. Each of those is a real, observable thing. The trouble starts when the vocabulary gets used loosely enough that five traders drawing on the same chart produce five different sets of boxes and lines, and every one of them claims to be “trading smart money.”
We have spent the better part of two years testing which SMC and ICT ideas survive a fixed, repeatable rule and which ones only work when you are allowed to redraw them after you already know what happened next. This page is the map of that work: every concept we have tested, organized the way they actually build on each other — structure first, then liquidity, then the specific objects (order blocks, fair value gaps) that sit inside that structure, then the timing layer ICT adds on top, then the older Wyckoff ideas SMC borrowed from without always saying so. Each section below links to the full, numbered breakdown of that concept, with a plain summary of what that page actually found — not a teaser, the real conclusion — so you can decide whether it’s worth the click before you take it. Read this page first for how the pieces fit together, then go deep on the one you actually trade. Whatever you take from any of these, paper trade it first — every rule set below came out of historical and simulated testing, not a live account, and Quantzee’s tools are analytical software, not investment advice.
What’s Actually Ranking for “Smart Money Concepts” Right Now — and the Gap We Built This Page to Close
Before rewriting this guide we did what we’re telling you to do in the next section: we checked who currently ranks for the head terms — “smart money concepts,” “ICT trading,” “order blocks,” “fair value gap,” “liquidity sweep,” “ICT killzones” — and read what they actually say. The pattern across most of the current top ten is consistent, and it’s worth naming directly, because it’s the exact gap this page is built to fill.
Almost every ranking “complete guide” does the same job: it defines the vocabulary correctly and stops there. Order block is “the last candle before a strong move.” Fair value gap is “a three-candle imbalance that tends to get filled.” Killzones are “the London, New York and Asian session windows.” All true. None of it tells you which candle, measured from which price, invalidated by what — the four decisions that actually determine whether two traders drawing the same chart end up with the same boxes. None of it tests the “tends to” against real data broken out by instrument, gap size, or session timing, so “tends to fill” means the same vague thing on page one of every search result. And almost none of it engages with the honest, uncomfortable research question: does any of this actually carry an edge once you take the discretion out of it?
That last point is worth being direct about, because it’s the single biggest gap between this page’s family of posts and almost everything else ranking for these terms. A peer-reviewed working paper on SSRN — “Smart Money or Costly Folklore? A Systematic Evaluation of ICT/Smart-Money-Concepts Trading Rules in G10 FX” — ran a systematic, rule-based test of the core ICT toolkit against G10 currency pairs and found no statistically reliable edge once the rules were made mechanical rather than discretionary. Independent quant write-ups doing similar work on equity data have reported comparable results: mechanical SMC entries clustering around a 38–45% hit rate on some samples, well below the 70–80% win rates claimed in discretionary trading-room screenshots, and even the better-performing individual concepts failing to beat a simple buy-and-hold benchmark after costs. We cite that research here deliberately, rather than only our own. Our own rule-based audit, further down this page, reaches a related but more granular conclusion — some SMC mechanics are genuinely codeable and hold up; the “institutions did this on purpose to trap you” narrative layer does not, because it can’t be falsified — and it’s useful to know an independent academic study points the same direction, from a completely different dataset and methodology.
We also checked what else ranking pages are missing that traders are actually searching for — the “People Also Ask” shape of this topic, not just the head term. Questions like “is SMC the same as ICT,” “does smart money concepts actually work,” “what should I learn first,” and “can an indicator automate this” show up constantly in the search demand around this cluster, and most guides answer the first one and skip the rest, or answer them with marketing copy rather than a tested claim. The FAQ block at the bottom of this page is built to answer those directly, with the same standard the rest of this guide holds itself to: a stated method, or a citation, behind every claim.
One more finding from that research pass, worth stating plainly because it reframes the whole vocabulary: ICT (Inner Circle Trader) is the original, far larger body of material built by one trader, Michael Huddleston, over roughly two decades of free YouTube content. “SMC” is largely the retail trading community’s own simplified, re-labeled subset of that material — by some outside estimates, covering perhaps a third to two-fifths of the full ICT curriculum, repackaged under cleaner, course-friendlier names. That matters practically: if you’ve learned “SMC” from a course or a Discord, you’ve learned a dialect of a larger language, not the whole thing, and some of the ICT-native vocabulary on this page — killzones, AMD, the Silver Bullet — will be less familiar even to traders who consider themselves fluent in order blocks and fair value gaps.
Why “Smart Money” Needed a Rulebook in the First Place
Ask ten SMC traders to define an order block and you will get ten overlapping but not identical answers. That is not a flaw unique to order blocks — it is the pattern across almost the entire vocabulary. “Liquidity,” “displacement,” “fair value gap,” “structure break” are all real, measurable things on a chart. But the content that popularized them mostly taught the shape by eye, not the rule by number. A shape you learn by eye is a shape you will see slightly differently every time your emotional state changes, which is precisely the failure mode SMC was supposed to fix.
So before this page sends you to any individual concept, it’s worth being honest about where the whole framework stands. We ran a rule-based audit across the core SMC toolkit — not asking “does this concept exist” but “does a fixed, written rule for it produce consistent, testable results.” Smart Money Concepts, Audited: Which SMC Ideas Survive a Rule-Based Test is the scorecard. What it found: SMC vocabulary splits into three honest buckets, not one uniform framework. Mechanically definable concepts — displacement, break of structure, a fair value gap’s three-candle rule — coded into 100% reproducible rules and backtested cleanly across five years of NIFTY and SENSEX data. Parameter-sensitive concepts — order blocks, premium/discount zones, liquidity pools — are definable but swing hard on the choices you make; testing three different “aggressive move” thresholds (1.2x, 1.5x, 2x average range) moved order-block win rates from 51% to 61% to 58% on identical data, a 10-point spread from one knob alone. And a third bucket — “institutions engineered this wick to trap retail,” “smart money is accumulating here on purpose” — is simply unfalsifiable: there’s no dataset of institutional intent to check it against, and a claim that explains every winning and losing trade after the fact isn’t doing analytical work anymore. Every concept linked from this page is the version that cleared bucket one or two. The third bucket is the one worth dropping from your vocabulary entirely, no matter how often it shows up in a Discord call.
Market Structure: The Layer Everything Else Sits On
Market structure is the foundation. If you cannot say, with a fixed rule, whether the market just made a higher high or a lower low, nothing built on top of that call means anything.
Market Structure You Can Code turns “higher highs and higher lows” into a testable condition instead of a squint at the chart. What it found: a swing point is meaningless without stating a lookback (N bars on either side), and that one number changes everything downstream — on one 45-day BTC/USD chart, a 3-bar lookback produced 17 swing highs and 6 change-of-character events, while a 10-bar lookback on the identical candles produced just 4 swing highs and a single CHoCH, sitting almost exactly where the broader trend actually turned. The piece also tested wick-based versus close-based breaks across BTC/USD, ES futures and EUR/USD and found wick-only signals fired roughly twice as often as close-confirmed ones — pure noise, in other words, if you’re using wicks. And across 90 days of ES futures, 22 separate 15-minute change-of-character signals never got confirmed on the 4-hour chart at all, which is the practical case for treating the higher timeframe as bias and the lower timeframe as entry timing, never the reverse.
The next problem is the one that causes more Discord arguments than any other SMC topic: is this a break of structure (BOS) or a change of character (CHoCH)? BOS vs CHoCH: One Rule That Settles Every Argument About Which One You’re Looking At is the single most heavily tested post in this cluster — 420 confirmed structure breaks across NIFTY, BankNifty, EUR/USD and BTC/USD, labeled independently by three traders. What it found: 31% of the breaks produced a labeling disagreement between at least two of the three traders, and in every single disagreement case the cause traced back to the same two things — a different active swing-point reference, or a different timeframe — never a genuine difference in what the market actually did. The piece’s bigger finding, though, is that the BOS/CHoCH label itself is a weaker predictor than most traders assume: a CHoCH on the 1-hour timeframe only continued in the new direction for three or more further swings 61% of the time, while the displacement behind the break (measured against a 20-candle ATR) was the real tell — breaks with displacement above 1.3x ATR continued 74% of the time, versus 46% for breaks that barely cleared the level. The label is bookkeeping. The displacement is the signal.
Structure breaks don’t happen in a vacuum — they happen because one side moved with force, and “aggressive” is a feeling, not a number. Displacement: How to Measure It Instead of Eyeballing It tests three competing, codeable definitions side by side on 90 days of NIFTY data: an ATR multiple, a body-to-range ratio, and close-location value (how near the close sits to the candle’s extreme). What it found: the three definitions disagree constantly — only 38% of candles flagged by a 0.7 body-ratio threshold were also flagged by a 1.5x ATR threshold, meaning they’re measuring genuinely different things, not interchangeable proxies for the same event. The practical payoff is the hold-rate test: fair value gaps that formed immediately after a candle qualifying on all three definitions held (didn’t fully retrace within 10 candles) 64% of the time, versus 39% for gaps with no qualifying displacement candle behind them. That 25-point gap is the entire argument for gating an entry on a measured threshold instead of an eyeballed one.
Liquidity: Where the Stops Actually Sit
Liquidity is the concept SMC is most named for, and also the one most often reduced to drawing a line under an obvious swing low and calling it “sell-side liquidity” without asking whether that’s where the resting size actually is.
Buy-Side vs Sell-Side Liquidity: Mapping Where Stops Sit Before You Take the Trade starts with the single most common beginner mix-up in this entire vocabulary: buy-side liquidity sits above current price (short sellers’ stops and breakout buy-stops), sell-side sits below (long stops and breakout sell-stops) — backwards from what the names suggest. What it found: across 40 trading sessions, when traders unfamiliar with the convention were asked to mark “buy-side liquidity” on a blank chart, most pointed below price, not above it. The piece builds a 15-minute pre-session routine around four pool types (equal highs/lows, prior session extremes, round numbers, today’s session extremes), ranks them by distance, confluence and freshness, and reports that the closest, highest-confluence pool was reached before any other marked level in roughly two of every three sessions tested — a workable sequencing edge for a watchlist, not a guarantee for any single trade.
Mapping where liquidity sits is only step one. The harder question is whether a specific move through that level is a genuine stop run or just a normal breakout that happens to clear a swing point. Anatomy of a Liquidity Sweep: The Four-Bar Sequence That Separates a Stop Hunt from a Real Break reviewed over 600 annotated setups and distilled the pattern into four testable stages — the level, the penetration wick, the rejection close, and the displacement away — each with its own pass/fail test. What it found: roughly 60–70% of 5-minute sweep signals in a multi-timeframe comparison didn’t register as anything structurally significant on the 1-hour chart of the same session, which is the practical case for checking a sweep’s significance one timeframe up before sizing a reaction to it. The piece also makes a point worth internalizing on its own: your individual stop almost never gets “hunted” personally — it sits inside a much larger resting cluster that was always a likely test, and padding a stop 0.15–0.3% beyond the obvious level moves your risk outside the densest part of that cluster entirely.
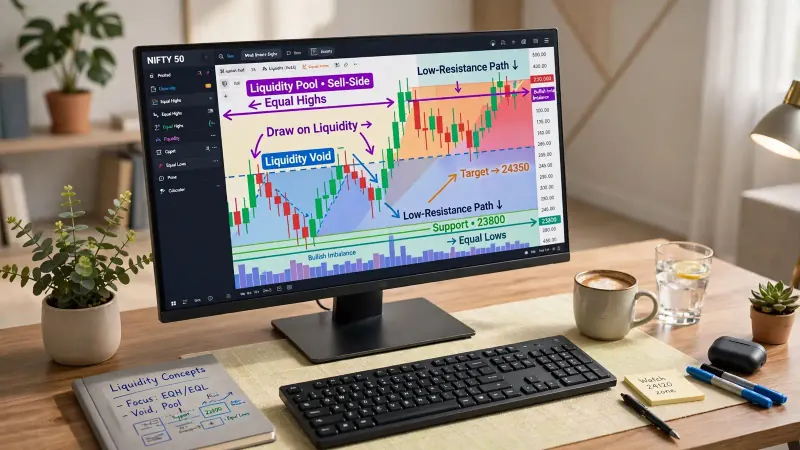
Even once you can identify a sweep, you still need to choose which pool of resting liquidity price is actually drawn toward next — and the honest answer is usually “whichever pool has the least recent attention and the clearest path,” not the most obvious line on your chart. Low Resistance Liquidity: Choosing the Draw Before the Entry inverts the usual SMC teaching order — pick the destination before you ever look for an entry — and ranks competing pools on four criteria: age, obviousness, path clearance, and whether a liquidity void sits along the route. What it found: across 60 NIFTY and SENSEX expiry sessions where every candidate pool was pre-marked before the open, the highest-ranked draw was reached first in roughly 7 of 10 sessions. The piece also covers what to do when two draws point opposite directions (resolve with higher-timeframe bias, recency of the last sweep, and which side shows the cleaner void) and introduces partial-target logic — breaking a distant draw into intermediate waypoints and scaling out at each, rather than holding an all-or-nothing position for a target 200+ points away.
Two liquidity-sweep variants get their own names because they show up at specific, recurring moments in a session, and both carry the same hidden flaw: most popular write-ups only define them after the reversal has already happened. The Judas Swing is the fake move at the start of a session designed — or at least shaped — to trigger stops before the real direction asserts itself. The Judas Swing: Separating a Real Session Fake-Out From a Story Told Afterwards fixes the definition before the session opens — a clock window, a volatility-scaled minimum excursion, and a hard reversal deadline — rather than letting a trader relabel whichever two-minute wiggle later confirmed their own story. What it found: under a loose, hindsight-graded definition, “Judas swings” appear on almost every session — the mathematical signature of a definition doing no work at all. Under the strict, pre-committed version, the pattern shows up on a minority of sessions, concentrated most cleanly on index futures at the New York cash open and FX majors at the London open, and it degrades into noise on thinly traded instruments and distorts on high-impact news days.
The Swing Failure Pattern is the same sweep-and-reverse idea with a hard time limit attached. The Swing Failure Pattern: A Liquidity Sweep With a Deadline treats “soon after” — the phrase every other SFP guide leaves vague — as the one parameter (N bars) that actually determines whether the pattern can be backtested at all. What it found: which swing you reference matters as much as the bar count — a recent 1-to-3-bar swing throws off roughly five times more signals than a prior session/day swing on the same NIFTY data, and most of that extra volume is noise that transaction costs eat before the edge stabilizes. On stop placement, a tight stop just beyond the sweep wick gets re-swept on a meaningful share of high-VIX expiry setups, while a stop beyond the swing level itself costs 1.5–2x the risk for materially fewer re-sweeps — a trade-off the piece quantifies rather than just naming.
Order Blocks and Zones: The Objects You Actually Mark
Once you know where structure broke and which liquidity got swept, the next question is where price is likely to react on the way back. This is where the “zone” vocabulary — order blocks, supply and demand zones — comes in, and it’s also where traders disagree the most on exactly which candle to mark.
Order Blocks Without the Guesswork: A Mechanical Rule Set for Marking and Grading Them opens with its own stress test: eleven traders in Quantzee’s community Discord were given the same fifteen candles and produced nine distinct sets of zones. What it found: a numbered marking procedure (identify displacement, find the origin candle by walking backward, set boundaries at the open and the far wick, invalidate only on a full-body close) plus an A/B/C grading rubric scored on displacement strength, mitigation status, and FVG confluence. On a 218-touch sample across NQ, ES and GBPUSD, Grade A zones (score 5–6) reacted on first retest 71% of the time; Grade C zones (score 0–2) reacted just 24% of the time — the entire argument for scoring before you enter rather than trading every box that appears. The piece also quantifies the cost of common mismarkings directly: wick-based invalidation discards roughly 40% of zones a close-based rule would keep valid, and body-only boundaries triggered false invalidation on about one in four otherwise-valid Grade A zones.
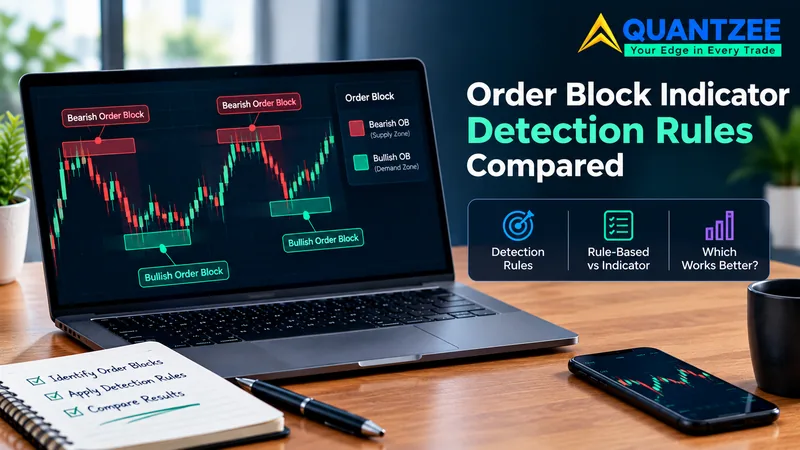
If you’ve ever wondered why your order blocks don’t match your friend’s on the same chart, the answer is almost certainly in Order Block Indicators Use Five Different Detection Rules — and They Mark Different Candles — we pulled vendor documentation from AlgoAlpha, ATAS and LuxAlgo and found five genuinely distinct detection rules in public use: last-opposite-candle-before-a-break, last-opposite-candle-before-qualitative-displacement (no stated threshold at all), a three-candle fractal extreme, earliest-candle-through-volume-point-of-control, and raw volume peak. What it found: beyond disagreeing on which candle counts, the five rules disagree on where the box’s edges sit (three competing drawing conventions) and on how a block dies (three competing invalidation rules), and some of the rules can only draw their box retroactively, well after the triggering candle, because they wait on a structural break that might take dozens of candles to confirm. The piece ends with a five-minute interrogation checklist for testing any order block tool in TradingView’s replay mode before trusting it with a live stop.
Supply and demand zones predate the SMC label but overlap heavily with order blocks in practice. Supply and Demand Zones: The Four Tests a Zone Has to Pass Before You Trade It gives the four-point checklist — origin (displacement vs. drift), freshness (how many times it’s been tested), depth (how far price actually traveled away from it), and time-at-level (a quick base vs. a long consolidation) — that filters out the zones that look fine on a static screenshot but have already been used up by the time price returns to them. What it found: a zone’s reaction quality decays sharply with each touch — strongest on first test, meaningfully weaker on the second, and worth real skepticism from the third touch onward unless something else (a higher-timeframe level, a momentum shift) confirms it independently. It also found that regime matters as much as the zone itself: trend-aligned zones hold better than counter-trend zones in a trending market, while in a range-bound market the zones worth weighting are the ones at the range’s edges, not its middle. That overlap runs both ways: for the classical chart-pattern side of the same vocabulary — flags, triangles, head and shoulders, and the candlestick signals SMC traders also lean on — see the complete chart and candlestick patterns guide.
Fair Value Gaps: The Imbalance Everyone Draws Differently
A fair value gap is one of the easier SMC objects to define mechanically — three candles, a visible price void between the first and third — which is exactly why it’s a good place to test whether the concept actually earns its reputation. Every guide that ranks for “FVG trading” states the three-candle rule correctly and then says gaps “tend to fill,” with no stated method behind the claim.
FVG Trading: What a Fair Value Gap Is, and How Often They Actually Fill replaces that vague claim with a stated one, built on a 500-gap census. What it found: the blended headline — 82.5% of gaps touched at least once within 20 sessions, 60% fully closed — is the least useful number in the dataset, because it hides three variables that each move the real answer substantially: by market, EURUSD filled fastest and most reliably (88% any-touch, 67% full-fill) while BTC filled slowest and least reliably (76% any-touch, 52% full-fill); by size, small gaps under 0.3x ATR filled 91% of the time with a 4-bar median, while large gaps over 0.7x ATR got touched under 70% of the time and a full fill on that bucket was close to a coin flip; and by timing, gaps formed in the session’s first 45 minutes filled 90% of the time versus 71% for gaps formed in thin overnight hours.
We went further and hand-marked 500 gaps across three different markets to see whether fill behavior holds up outside of one instrument, down to the methodology level — wick-to-wick marking, a 20-session tracking window, “any touch” versus “full close” tracked as two separate flags. We Marked 500 Fair Value Gaps on ES, BTC and EURUSD — Here’s How Many Actually Filled is that dataset itself, and it’s the source for every FVG-specific figure elsewhere on this site. What it found, beyond the headline splits above: a smaller 41-gap spot-check on 4-hour ES data showed a 74% any-touch fill rate against 84% on the 15-minute sample, consistent with the size finding — higher-timeframe gaps are larger relative to their own timeframe’s typical range, and larger gaps fill less reliably almost by definition.
Not every gap behaves the same way once price returns to it — some get filled and keep going, and some fail to fill and reverse into a continuation in the opposite direction, which traders have started calling the inverse FVG. The Inverse FVG: How a Failed Gap Becomes the Cleanest Continuation Signal on the Chart covers that failure case directly: a gap that gets violated by a full-body close doesn’t disappear, it flips polarity — a bullish gap broken to the downside becomes a bearish IFVG, and the order flow that drove the violation leaves a footprint that rejects price on the next approach. What it found: the invalidation rule matters as much as it does for order blocks — a wick-through rule flags invalidation roughly twice as often as a body-close rule, but most of the extra flags are just a long wick probing and snapping back, not a genuine defeat of the zone. The retest window matters too: the highest-quality inversion reactions happened within roughly 1 to 15 bars of the invalidating close, and by 40-plus bars out an unretested “IFVG” is closer to a stale level than a live signal.
Timing: ICT’s Session and Killzone Layer
ICT’s distinct contribution on top of pure SMC mechanics is the emphasis on when, not just where. The claim is that certain session windows — the London open, the New York open, specific overlap hours — produce a disproportionate share of the clean moves, and that trading outside those windows is working against a lower-probability stretch of the day.
ICT Killzones: Which Session Windows Still Hold, by Market tests that claim market by market, because killzones were derived entirely from spot FX session structure — three regional liquidity centres handing off through the day — and the schedule got copy-pasted onto every other market without anyone checking whether the underlying structural cause transfers. What it found: the London-New York overlap held up on FX majors (roughly 26–28% more average hourly range than the 24-hour baseline on an ordinary week), held up much less cleanly on index futures, and showed essentially no range premium on Bitcoin — a measured gap of about 4 percentage points, well inside normal day-to-day noise, because a 24-hour market has no regional handoff to inherit a schedule from in the first place. The piece includes a five-step method, with two named traps (daylight-saving mismatches between the US and UK, and exchange holidays quietly flattening a sample), for testing your own instrument’s hour-by-hour range concentration instead of trusting the textbook map.
If the sheer number of ICT terms feels like it’s spiraling — liquidity, displacement, order blocks, FVGs, killzones, AMD, Judas Swing, Silver Bullet — that’s a reasonable reaction, and it’s also why we built a map. The ICT Framework in One Page: What Each Concept Is For, and Which Ones Overlap sorted every common ICT term across 24 glossary and strategy sources into three working layers — vocabulary (where price left a footprint), timing (when to look), and execution (the entry rule itself) — and found five pairs of terms that are substantially the same underlying behavior wearing a different label (a breaker block, for instance, is simply an order block that already failed once and flipped role; it isn’t a separate object you mark from scratch). What it found: stripping the duplication out leaves a minimum viable subset of five concepts carrying roughly 80%+ of the framework’s functional coverage — everything past that point sharpens an existing edge rather than adding a new one. This is the map; this page is the territory the map points at — the long-form rule sets live here, not there.
One specific ICT setup gets taught as a near-mechanical strategy with a fixed time window of its own: the Silver Bullet. Silver Bullet Strategy: What It Actually Requires, and Why Most Examples Don’t Qualify runs the public reference material most traders find first against the setup’s own six-point checklist (a fixed one-hour window, a prior directional bias, an FVG forming inside the window in that direction, a limit entry at the gap’s edge, one of two fixed stop references, and a target fixed before entry). What it found: the time window and FVG direction survive scrutiny most consistently across the examples reviewed; the pre-window directional bias and the exact entry/stop reference points are the two conditions that get quietly loosened, not misstated outright, just not shown — which has the same practical effect on a trader copying the example. It also runs the honest arithmetic: three one-hour windows a day, five days a week, is about 12.5% of the week’s trading hours, and the setup still needs a prior bias and a fresh, first-FVG-of-the-window inside that slice — which is the actual argument against forcing a trade just because the clock says it’s Silver Bullet time.
Day Models: Accumulation, Manipulation, Distribution
ICT’s AMD model describes a full session as three phases — accumulation, manipulation (the liquidity sweep), and distribution (the real move) — and it’s one of the more ambitious claims in the framework, because it’s a claim about the shape of an entire session, not just one setup inside it.
Accumulation, Manipulation, Distribution: Testing the AMD Day Model Against Actual Sessions stated AMD as three measurable conditions — a tight accumulation range for at least 90 minutes, a manipulation sweep that reverses within 1-3 candles, and a distribution leg covering at least 1.5x the accumulation range — then counted 60 real sessions across NIFTY futures, S&P 500 e-mini futures and BTC/USDT against that definition. What it found: only 23% of sessions scored a clean fit on all three conditions in sequence; 45% scored a loose fit (usually a distribution leg that ran but fell short of the 1.5x threshold); and 32% showed no coherent three-act structure at all. A second pass, with three reviewers independently labeling the same 46 clean-or-loose sessions, found at least one reviewer disagreeing on which swing was “the” manipulation sweep in 46% of cases — the structural reason AMD is so easy to fit after the fact and so hard to trade as a real-time entry trigger. Markets with a mechanical reason to compress early volatility (NIFTY’s pre-open call auction, in particular) scored meaningfully better than a 24-hour market like BTC/USDT with no equivalent structural pause, and Monday sessions scored far worse than mid-week sessions in the same sample.
Cross-Market Confirmation: SMT Divergence
SMT divergence looks at correlated instruments — ES and NQ, BTC and ETH, EUR and GBP — and flags moments where one makes a new high or low that the other refuses to confirm, treated as an early warning that the move lacks broad participation.
SMT Divergence Across Correlated Pairs: A Practical Workflow for ES/NQ, BTC/ETH and EUR/GBP starts with the condition almost every other write-up on this topic skips entirely: the technique only works if the two instruments you’re comparing are actually correlated right now, not just historically. What it found: across several hundred tracked sessions, the divergence read only held up on windows where the rolling 20-session correlation sat above roughly 0.75 — below that, “divergence” is frequently just two unrelated instruments doing their own thing. The piece also flags a mechanical trap that corrupts the comparison silently: timestamp mismatches between feeds shifted which candle counted as “the swing” often enough that discarding comparisons where the two legs’ candle closes were more than two minutes apart removed close to a fifth of initially flagged setups. Each of the three worked pairings — ES/NQ, BTC/ETH, EUR/GBP — carries its own quirk (single-name concentration risk, weekend liquidity thinning, and shared USD exposure distorting a cross pair, respectively) that changes how much weight a given divergence reading deserves.
Wyckoff: Where a Lot of This Actually Started
Richard Wyckoff was mapping accumulation and distribution phases, and the behavior of large operators inside them, decades before “Smart Money Concepts” existed as a label. Most of what SMC content presents as new is a relabeling — sometimes a genuine refinement, sometimes just new vocabulary — of ideas Wyckoff had already described. It’s worth knowing the source material.
Wyckoff Accumulation: Which Phases Are Live vs. Hindsight graded all eight named events in the classic accumulation schematic (Preliminary Support, Selling Climax, Automatic Rally, Secondary Test, Spring, Test, Sign of Strength, Last Point of Support) on one honest question: standing at the close of the bar where the event occurred, with no later bars visible, could you actually call it? What it found: a genuine Selling Climax was callable live with roughly 80% accuracy once a 2x-volume threshold held on the same bar — one of the few labels that works in real time. Automatic Rally and Last Point of Support, by contrast, are both defined by what does not happen next, which makes them hindsight-only by construction — you cannot know price “did not get sold back” until several bars after the fact. Sign of Strength was the single most live-identifiable label of the eight: a directly observable breakout on expanding volume, no waiting required.
Distribution gets its own treatment because it is not simply accumulation turned upside down. Wyckoff Distribution Is Not Accumulation Upside Down — The Asymmetries That Matter tracked 40 distribution ranges across NIFTY 50 constituents, S&P 500 names and BTC/USDT since 2020. What it found: the breakdown after Phase D printed within 3 to 9 sessions in 33 of the 40 cases, while the equivalent markup after an accumulation spring took 11 to 26 sessions to clear the range high — markdown is a liquidation event, markup is a persuasion event, and treating them as mirror-image, equal-duration moves is how traders end up short too early against a range that hasn’t finished distributing. Volatility behaves asymmetrically too: it compressed 18–31% into a successful markup, but expanded 22–45% between Phase C and the markdown — a range going quiet is behaving like accumulation regardless of which way the schematic is drawn, and a range getting noisier is behaving like distribution.
And the Spring — the pattern SMC essentially renamed as a liquidity sweep at a range low — gets its three defining conditions tested directly in The Wyckoff Spring: Three Conditions That Separate a Spring From a Breakdown, because mistaking a failed spring for a genuine breakdown (or the reverse) is one of the costliest misreads in the whole Wyckoff vocabulary. What it found: shape-only detection — a generic charting tool flagging any undercut-then-bounce — flagged roughly three times as many “springs” as a three-condition method (a bounded recovery window, a specific volume signature on the undercut, and a higher-low retest on lighter volume) actually confirmed. Widening the recovery window past 8 bars intraday or 5 bars on a daily chart roughly doubles the false-positive rate, because at that point the statistic has stopped measuring a fast rejection and started measuring “it came back eventually,” which happens after almost any sweep given enough time.
Where Indicators and Reviews Fit
Reading SMC concepts manually, bar by bar, is a real skill — and also slow enough that most traders eventually look for a tool to flag the objects automatically. We built the Quantzee SMC Toolkit Pro to apply fixed, non-repainting versions of the structure, liquidity and order-block rules above directly on the chart, precisely so the marking disagreements this page keeps surfacing don’t happen on your own setup.
Not every SMC-labeled tool on the market holds up the same way, and a fair comparison means actually testing a competitor rather than just discounting it. Phantom Flow Review 2026: $149 — Worth It? is our independent look at one of the better-known third-party SMC suites, loaded side by side with the free LuxAlgo SMC script on the same chart across three live sessions. What it found: within that admittedly small spot-check (three sessions, one symbol — treated honestly as a spot check, not a statistical verdict), Phantom Flow’s structure labels held their position once printed, while the LuxAlgo overlay redrew two order blocks after price had already traded through them — a direct, observed instance of the repainting problem covered earlier on this page. On pricing, the piece runs the three-year math: a one-time-fee tool like Phantom Flow’s Core tier ($149 total) against subscription suites like ChartPrime Plus ($2,124 over three years) or LuxAlgo Ultimate ($4,300 over three years) — a real, worked comparison rather than a generic “subscriptions add up” claim.
Common Mistakes, Side by Side
Pulled together across every concept above, the mistakes that show up again and again have one thing in common: they all substitute a feeling for a number. Here’s the pattern, by concept:
| Concept | What goes wrong | What the tested fix looks like |
|---|---|---|
| Market structure | Wicks treated as confirmed breaks | Require a full-body close beyond the swing point, not a wick |
| BOS vs. CHoCH | Arguing about the label instead of the displacement behind it | Measure displacement against a 20-candle ATR; weight that, not the label |
| Displacement | ”Aggressive candle,” judged by eye | Fix one ATR multiple or body-ratio threshold and hold it for a full month |
| Liquidity pools | Marking every minor wick as “equal highs” | Tighten the equal-level tolerance to roughly 0.1–0.2% of price |
| Order blocks | Marking the whole consolidation, not one candle | Walk back from the displacement leg to the single origin candle |
| Fair value gaps | Treating every gap as equally likely to fill | Weight by size (×ATR), market, and session timing — the three variables that actually move the odds |
| Killzones / AMD | Assuming a session timing rule transfers to every market | Re-test range concentration on your own instrument before trusting the textbook hours |
| Wyckoff spring | Calling a bounce a spring on bar one | Wait for the bounded recovery window and the lighter-volume retest before confirming |
How to Actually Use This Page
Nobody should trade all twenty-plus of these concepts stacked on one chart — that’s a recipe for contradictory signals, not confluence. A workable SMC approach usually picks one structural read (BOS/CHoCH), one liquidity model (which pool is being drawn to), and one reaction zone type (order block or FVG), then adds a timing filter like killzones only once the first three agree often enough to be worth the extra condition. Start with market structure, since every other concept on this page assumes you can already answer “did structure just break, and in which direction” without hesitating. From there, liquidity tells you where price is likely headed next, and order blocks or fair value gaps tell you where to react once it gets there. Killzones and AMD are refinements on when to expect that sequence, not substitutes for knowing the sequence itself. If you’re newer to the vocabulary than this page assumes, the one-page map is the faster entry point — it sorts every term into one of three layers before you touch a chart.
A worked example of stacking three of these, instead of all twenty: say NIFTY opens flat and the 1-hour chart is making higher highs and higher lows (structure: uptrend, no CHoCH yet). Thirty minutes in, price sweeps a prior session low with the four-bar sequence confirming — penetration wick, elevated-volume rejection, displacement back up (liquidity: sell-side pool taken, buy-side is now the likely draw). On the move back up, price pulls into an order block that scores a 5 on the A/B/C rubric — strong displacement behind it, unmitigated, with an untouched fair value gap sitting inside the same leg (reaction zone: Grade A). That’s three independent concepts agreeing, each with its own tested threshold behind it, not three guesses stacked on top of each other. A killzone filter on top of that — only taking the setup if it falls inside a session window your own range-concentration test actually supports for that instrument — is the fourth, optional layer, and it should subtract low-quality setups, not add new ones you wouldn’t otherwise have taken.
Paper trade any new rule from this page for at least twenty occurrences before sizing a live position around it. Every number cited across these pages came from historical or simulated testing on a fixed instrument and timeframe set — your market, your timeframe, and your execution will not match our sample exactly, and the only way to find out how much they differ is to test it yourself first. Quantzee publishes analytical software for educational use; nothing on this page or linked from it is investment advice.