Expectancy in trading is the average amount a rule makes or loses per trade once every win, every loss and every cost is counted. It's the one number that tells you whether a set of rules has an edge at all. The catch most explainers skip: expectancy belongs to a setting, not to a strategy. When we ran one plain SuperTrend rule across 1,080 cost-applied parameter sets, only 226 of them (about 21%) finished with positive expectancy, and 391 (36%) lost the whole notional. A positive number from one trade log tells you about one cell in a grid you haven't looked at yet.
This post covers the trading expectancy formula once, then spends its time on what the formula can't tell you: how costs flip the sign, how picking the top setting inflates the figure, and how many trades it takes before the number means anything.
The trading expectancy formula, in both forms
There are two ways to write it, and they answer slightly different questions.
Money form: expectancy per trade = (win rate × average win) − (loss rate × average loss).
With a 40% win rate, a $300 average win and a $150 average loss, that's (0.40 × 300) − (0.60 × 150) = $120 − $90 = $30 per trade. Simple, and fine for a single account that never changes size.
R form: expectancy = the mean of each trade's net result divided by the risk taken on that trade. If you risked $150 and made $300, that trade is +2R. If you lost the full $150, it's −1R. Average all of them and you get expectancy in R.
Use the R form. It survives changing position size, which the money form doesn't. Double your size halfway through a log and the dollar expectancy jumps, though the rule hasn't improved at all. That matters here, because the grid we're about to read was run with full equity reinvested on every trade, so its dollar figures grow and shrink with the account. If you want the money side of R, our risk-reward ratio glossary entry covers how the two sides of a trade relate, and the position size calculator turns a fixed R into a share or contract count.
Positive expectancy means above zero after costs, and nothing else
You'll see pages that call 0.2R "good" and 0.5R "excellent". Those bands are someone's opinion about a sample you can't see. The one fixed threshold is zero, and it has to be zero after costs. A rule with positive expectancy before costs and negative after is a rule that pays its broker.
"After costs" has to include four things:
- Commission and exchange fees, both sides of the trade.
- The spread you cross at entry and again at exit.
- Slippage against the fill price your backtest assumed.
- Funding or financing, if you hold leveraged positions overnight.
The pineconnector.com write-up makes the same point: according to their September 2026 guide, zero after costs is the only threshold that doesn't depend on the trader. We agree, and the grid below shows why it's not a technicality.
What 1,080 settings of one rule look like
Here's the dataset. It's published in full on our SuperTrend backtest results grid, and nothing below is re-derived from memory.
- Rule: plain SuperTrend trend-following. Long or short, flip on signal, always in the market, no pyramiding.
- Settings: ATR period 7, 10, 14, 20 or 30, multiplier 1.0 to 5.0 in 0.5 steps. That's 45 combinations.
- Timeframes: 1m, 3m, 5m, 15m, 30m, 1h, 4h and 1d.
- Instruments: BTC, Gold and Silver. Gold and Silver use Dukascopy 1-minute data from 2020-01-01 to 2026-10-20 (about 6.8 years). BTC uses Delta Exchange data from 2023-12-29, so it covers about 2.8 years.
- Fills: next bar's open after the flip bar closes, so there's no lookahead.
- Engine: vectorbt, full equity reinvested each trade.
- Costs: stated round-trip assumptions of 15 bps for BTC, 4 bps for Gold and 8 bps for Silver, plus a zero-cost copy of every row.
That gives 2,160 rows: 1,080 with costs applied and 1,080 at zero cost. The methodology and cost reasoning live in the SuperTrend settings guide.
One honest caveat before the numbers. The grid has an expectancy column, but because of full reinvestment it's a dollar figure that scales with a compounding account, not a clean R value. So we don't quote per-trade expectancy sizes from it here, and you shouldn't compare them across rows. What does carry over is the sign. Positive or negative expectancy doesn't depend on position size, and in this grid the count of positive-expectancy rows matches the count of profitable rows exactly.
Here's how those signs fall by timeframe, cost-applied rows only (135 rows per timeframe):
| Timeframe | Positive with costs | Positive at zero cost | Wiped out (−100%) | Median trade count |
|---|---|---|---|---|
| 1m | 0 | 0 | 135 | 29,776 |
| 3m | 0 | 0 | 120 | 12,614 |
| 5m | 0 | 11 | 96 | 10,944 |
| 15m | 2 | 57 | 30 | 3,205 |
| 30m | 19 | 88 | 10 | 1,584 |
| 1h | 44 | 89 | 0 | 767 |
| 4h | 97 | 118 | 0 | 228 |
| 1d | 64 | 71 | 0 | 51 |
Source: our data, the published 2026-10-21 sweep. Zero-cost counts are a diagnostic baseline. Nobody trades at zero cost, so no zero-cost row is a result anyone could actually get.
Read that table as the answer to "what is the expectancy of SuperTrend?" There isn't one. Across the same rules, 226 cost-applied cells are positive, 854 aren't, and 391 of those 854 went to zero. All 135 of the 1-minute cells were wiped out. The 4-hour row has 97 positive cells out of 135. Same indicator, same code, same fill logic. The setting is doing most of the work.
Instrument matters as much as timeframe. On Silver's 4-hour chart, all 45 settings finished positive with costs. On BTC's 1-hour chart, none of the 45 did. Anyone quoting "SuperTrend expectancy" from one of those two cells would be telling you something true about that cell and nothing about the other.
Costs are the dominant term once trade count climbs
The fastest way to see the cost wedge is to compare the two columns. At zero cost, 433 of the 1,080 cells have positive expectancy. With costs, 226 do. So 207 settings flipped from a positive signal to a non-positive result purely because of trading costs. That's a cell where the rule did find something, then paid all of it away.
Where those flips happen is the useful part. The 30m timeframe had 69 of them, 15m had 54, and 1h had 45. On 1m and 3m there was nothing to flip, because those cells weren't positive even before costs. The signal itself had no edge at that speed.
Some simple arithmetic shows why. Take the 4 bps round trip assumed for Gold. A cell with 340 trades over 6.8 years pays roughly 340 × 0.04% ≈ 13.6% of notional in costs over the whole run, before compounding. A 1-minute cell at the median of 29,776 trades pays 29,776 × 0.04% ≈ 1,191% of notional. No trend signal earns that back. The per-trade edge has to beat the round-trip cost on every single trade, and at high frequency the edge per trade gets smaller while the cost per trade stays fixed.
Here's the practical test we use. Before you trust any expectancy figure, multiply your round-trip cost by the trade count and set it next to the gross profit. If the cost line is a big share of the gross, small changes in fill quality will decide whether the system makes money, which is also why copying one rule onto faster timeframes so rarely helps. The tradezella.com article on trading expectancy, for comparison, works its example ($400 average win, $250 average loss, 45% win rate, $42.50 per trade) without costs at all. That example is fine for teaching the arithmetic. It's not a number to plan around.
Choosing the top cell inflates the number you report
This is the part no ranking page on expectancy deals with. When you search 45 settings and keep the winner, the winning figure is partly a measure of how many settings you searched.
Gold's 4-hour chart shows it clearly. The top cell, ATR 30 with a 2.5 multiplier, returned +153.3% with costs over the window. Its neighbours look like this:
- ATR 30, multiplier 2.0: +67.6%
- ATR 30, multiplier 3.0: +142.5%
- ATR 20, multiplier 2.0: +36.4%
- ATR 20, multiplier 2.5: +91.4%
- ATR 20, multiplier 3.0: +124.1%
The median of all 45 Gold 4-hour cells was +48.1%. So the honest headline for "SuperTrend on Gold 4h" is closer to the middle of that spread than to the top. If a live account landed at +48% where the backtest promised +153%, nothing broke. The trader just reported the luckiest cell.
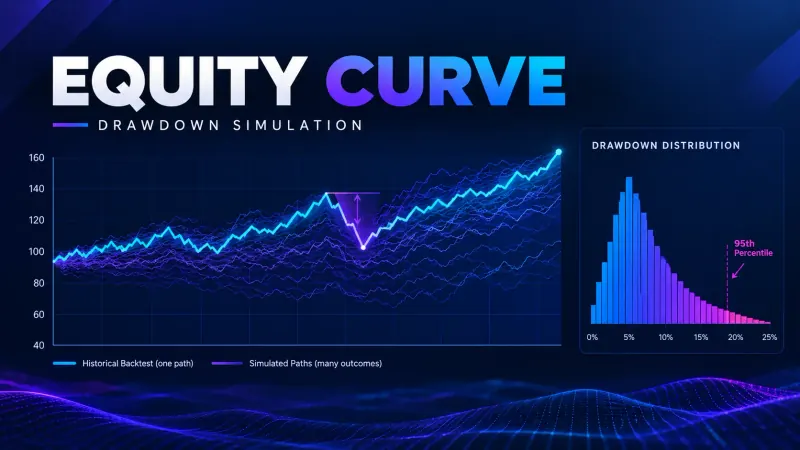
The one-line defence: report expectancy for the family of nearby settings, not just the winner. Show the median and the spread of the cells around your pick. If the neighbours are also positive, the edge is probably a property of the rule. If your pick is a lone spike surrounded by losers, it's probably a property of the sample. Our stress-testing checklist turns this into a repeatable step, alongside regime and cost shocks.
How many trades before expectancy means anything
There's no magic trade count, and anyone who gives you "30" or "100" as a universal rule is skipping the part that matters. The useful idea is the standard error of the mean. Per the NIST/SEMATECH engineering statistics handbook, the confidence limits for a mean shrink with the square root of the sample size and widen with the spread of the data.
Applied to trading: standard error of expectancy ≈ (standard deviation of trade results in R) ÷ √(number of trades).
Two systems can have the same expectancy and need very different sample sizes. Take two rules, both at +0.2R. Rule one's trades have a standard deviation of 1.2R. Rule two, which lets winners run, has 2.4R. To get the expectancy two standard errors clear of zero, you need roughly (2 × spread ÷ expectancy)² trades:
- Rule one: (2 × 1.2 ÷ 0.2)² = 144 trades.
- Rule two: (2 × 2.4 ÷ 0.2)² = 576 trades.
Those are illustration figures, chosen to match the worked pair pineconnector.com publishes (144 versus 576 trades for the same 0.2R). The lesson is the shape, not the numbers. Trend-following rules with fat right tails need a lot more trades to prove themselves, because a few big winners carry the result.
Look back at the grid with that in mind. The 1d cells had a median of just 51 trades. BTC's top 1-day cell made +61% on 12 trades. That's a real backtest result, and it also tells you almost nothing about the rule's expectancy. Twelve outcomes can't separate a thin edge from a good run.
Expectancy versus profit factor and win rate
The three numbers answer three different questions.
Win rate answers "how often?" It says nothing about size. A rule can be right most of the time and still bleed money. The traderssecondbrain.com guide works through a system with a 62% win rate and an expectancy of −0.117R. It's constructed, not measured, but the arithmetic is sound: small frequent wins, larger occasional losses. Our grid runs the other way. The highest win rate of any cost-applied cell was 50.4% (Silver 4h, ATR 30, multiplier 5.0), and plenty of profitable cells sat near 40%. Trend rules win less than half the time and make it back on size.
Profit factor answers "how much was won for every dollar lost?" It's gross profit divided by gross loss. It hides trade count completely, so a profit factor of 2.0 from 8 trades and from 800 trades look identical. Our piece on why profit factor is the metric most likely to make a bad strategy look good goes through that trap in detail, including a 620-trade example with a profit factor of only 1.15 that was still sound.
Expectancy answers "what does one more trade earn, on average?" It's the only one of the three that connects directly to what an account will do over the next 100 trades, provided the sample is big enough and costs are in.
Is expectancy the same as profit factor? No. Both use the same wins and losses, but profit factor is a ratio and expectancy is an average per trade. You can have a high profit factor with a tiny expectancy if the system trades rarely and wins small.
Expectancy per unit of time, not only per trade
Per-trade expectancy ignores how often the edge shows up. Compare:
- A 0.1R edge taken 200 times a month: about 20R a month.
- A 0.4R edge taken 4 times a month: about 1.6R a month.
The second has four times the per-trade expectancy and roughly a twelfth of the monthly result. It also has far less data to stand on. After a year it has 48 trades, while the first has 2,400. Go back to the sample-size maths and you can see the first rule's expectancy is pinned down much faster.
The grid adds a warning to that. Higher frequency only helps when the per-trade edge clears costs. On every 1m cell in our data, it didn't. More trades just meant more cost. So the real question is expectancy after costs, times trade frequency, with enough trades to trust the first number.
The honest limit: backtested expectancy is an upper bound
A backtest's expectancy is the most you should expect live, not the likely result. The U.S. Commodity Futures Trading Commission's advisories repeat the same warning: hypothetical results don't reflect real fills, liquidity or the fact that nobody traded them. In our experience, three leaks do most of the damage:
- Fills. The backtest assumed the next bar's open. Live, you get the open plus whatever the book gave you. On a cell that pays costs 30,000 times, a fraction of a basis point per trade is the whole edge.
- Missed signals. A platform restart, a late alert or a skipped trade on a bad day. Trend rules make most of their money on a few trades, so missing one of them hurts more than the trade count suggests.
- Softened rules. The stop got moved "just this once." The rule live is no longer the rule you measured, so the expectancy you measured no longer applies.
We've seen each of these cut a live result below its backtest, and our guide to why backtests don't match live trading walks through the full list with checks for each. Quantzee builds analytical tools for this kind of measurement. It doesn't give trade signals or advice, and nothing in the grid is a forecast.
A short checklist before you trust an expectancy figure
- Is it in R, not dollars, so position-size changes can't fake it?
- Are commission, spread and slippage in, at realistic levels for your venue?
- What does cost × trade count look like next to gross profit?
- What's the median expectancy of the nearby settings, not just the chosen one?
- How many trades, and what's the standard error at that count?
- What does it look like per month, not just per trade?
- Which of the three live leaks will it face, and how much edge is there to absorb them?
If you can answer all seven, the number means something. If you can only answer the first, it's a figure from one cell of a grid you haven't looked at.