Educational Disclaimer: This is educational content for informational purposes only. It is not investment advice. Trading involves significant risk of loss, and past backtested or live performance does not guarantee future results. Do your own research and consult a licensed financial advisor before making any trading decision.
You spent a weekend building a strategy. You ran it through two years of history. The equity curve climbed smoothly, drawdowns stayed shallow, and the win rate looked good enough to trade real size. Then you went live — and within two weeks the results looked nothing like the backtest. Entries fired at different prices than the chart implied. Signals that looked obvious in hindsight never triggered in real time. The strategy that returned 40% in simulation is flat, or worse, in the market.
This is one of the most common — and most misunderstood — problems in retail trading. It is not usually bad luck, and it is rarely proof that “backtesting doesn’t work.” In almost every case, the gap between backtested and live performance traces back to a specific, identifiable cause. This article walks through the four biggest ones — repainting, look-ahead bias, slippage, and execution drift — explains exactly how each one distorts your numbers, and gives you a practical checklist to close the gap before you risk real capital.
⚡ Key Takeaways
- Repainting indicators redraw past signals using information that wasn't available at the time — a backtest built on repainted history is testing a strategy you can never actually trade
- Look-ahead bias is the silent killer of backtest validity: any calculation that references a full candle before that candle has closed inflates results in ways that vanish live
- Overfitting (curve-fitting to one historical window) is one of the largest single causes of backtest-to-live divergence — a strategy tuned to 500 past trades often has fewer real degrees of freedom than that; walk-forward validation across multiple rolling windows is the fix
- Slippage and spread are the single largest source of the "my backtest was better" complaint on liquid instruments traded at scale — a strategy with a thin per-trade edge can be entirely consumed by execution cost
- Regime dependence (a strategy backtested only in a trending or only in a ranging market) silently inflates results unless the test window deliberately covers trend, range, and high-volatility conditions
- Execution drift (order queueing, partial fills, broker latency, and manual hesitation) adds a second, separate layer of degradation on top of slippage that most backtests never model at all
- Closing the gap requires a repeatable checklist — non-repainting confirmation, out-of-sample and walk-forward validation, realistic cost modeling, regime coverage, and forward/paper testing — not a single fix
About the Author — Rajeev Gupta: Over 15 years of active trading across global indices, forex majors (EUR/USD, GBP/USD, USD pairs), and crypto (BTC/USD) — spanning structured options selling, directional options buying during high-volatility events, and long-term equity positioning — I built Quantzee specifically to close the gap between backtested theory and live execution. Every indicator in the Quantzee suite is designed non-repainting from the ground up, precisely because this article’s problem is the one retail traders hit most often. This piece reflects that experience and is presented for educational purposes only — not investment advice.
The Core Problem: A Backtest Is a Simulation, Not a Time Machine
Every backtest makes an implicit promise: “if you had traded this exact strategy on this exact history, this is the result you would have gotten.” The moment any part of that promise is broken — even slightly — the backtest stops describing a strategy you can trade and starts describing a strategy that only exists on paper.
The gap shows up in five independent places, and most traders only ever discover one of them, fix it, and assume the problem is solved. It rarely is. Each cause below can exist on its own or stack with the others, and they require different fixes.
Cause 1: Repainting Indicators
Repainting is the most damaging and least understood cause of backtest-to-live divergence, because it corrupts the data your backtest is built on before you ever place a trade.
What Repainting Actually Means
A repainting indicator changes its own past output after new data arrives. On a chart, this looks completely normal — you scroll back through history and every signal appears clean, well-timed, and profitable. But that clean appearance is an illusion: the indicator recalculated those historical signals using information from candles that, at the actual moment in time, had not closed yet.
The clearest example is any signal built on an unconfirmed pivot or a mid-candle value. Say an indicator marks a “buy” signal at a swing low. If that swing low is identified using price action that continues for several bars after the low — the indicator needs to see the bounce to know it was a low — then the signal you see on a historical chart was drawn with future knowledge. In real time, that same bar would not have shown a buy signal until several bars later, by which point price had already moved.
Why This Wrecks a Backtest Specifically
If your backtesting engine reads signals directly off a repainting indicator’s historical output, it is silently cheating. It enters trades at price levels that were only knowable in hindsight. Entries look perfectly timed because they were drawn with the benefit of seeing what happened next. The backtest’s win rate, average trade, and equity curve all inherit this hindsight advantage — and none of it is achievable live, because live you only ever see the present bar, never the future one.
This is why a strategy can show an 80% backtested win rate and a coin-flip live win rate using the exact same indicator settings. The backtest was never testing the strategy you thought it was.
How to Check for Repainting
- Bar-replay test. Load the indicator on a chart, use your platform’s bar-replay or “walk forward” tool to step through history one candle at a time, and compare each signal as it first appears against where it eventually settles. If a signal moves, disappears, or shifts bars after it first fires, the indicator repaints.
- Confirmed-candle rule. Any indicator logic that references
close,high, orlowof the current, still-forming candle is a repaint risk by construction. Signals should only be calculated on the previous, fully closed candle. - Cross-check against alerts. If you have historical alert logs (from TradingView or your platform), compare the alert timestamp and price against where the signal appears on the chart today. A material difference confirms repainting.
- Ask the indicator’s documentation directly. A properly built, non-repainting indicator should explicitly document this, and its logic should hold up under the bar-replay test above without exception.
Cause 2: Look-Ahead Bias in the Backtest Engine Itself
Look-ahead bias is a close cousin of repainting, but it lives in the backtest engine’s mechanics rather than in the indicator’s math. Even with a genuinely non-repainting indicator, a poorly built backtest can still leak future information into past decisions.
The Classic Failure Modes
Same-bar entry and exit using close. If your backtest enters a trade at the close of a signal bar and then checks whether that same bar’s high or low would have hit a stop or target, it is using information that was not known until the bar finished forming. In live trading you cannot enter at a close price and simultaneously know whether that bar’s extremes will be favorable or unfavorable to you.
Using end-of-day data intraday. A backtest that references a daily close, a daily VWAP, or a daily high/low anchor as if it were known mid-session — before the session actually closed — is testing against numbers that did not exist yet at the decision point.
Survivorship-adjusted universes. Less relevant for single-instrument index or forex strategies, but critical for basket or portfolio backtests: testing only against instruments that are still actively listed and liquid today silently excludes the ones that failed, inflating the apparent success rate of the strategy.
Parameter optimization on the full dataset. If you tune a strategy’s stop-loss, target, or lookback period by testing every combination against the entire historical dataset and picking the best result, you have not built a strategy — you have curve-fit a set of parameters to that specific slice of history. The backtest will look excellent because it was reverse-engineered to look excellent; it has no reason to generalize to future, unseen data.
How to Check for Look-Ahead Bias
- Sequential-only data access. Confirm your backtest engine processes bars strictly in chronological order and only exposes data up to and including the currently processed bar — never beyond it.
- Separate entry and outcome logic. Entry decisions should be made using only the previous closed bar. Stop/target checks on the entry bar itself should be treated conservatively (assume the worse of the two outcomes if both could plausibly have happened within that bar) rather than assumed favorable.
- Split your data before you tune anything. Reserve a meaningful chunk of history — commonly the most recent 20–30% — that you do not touch during parameter selection. Only run it once, after your parameters are locked in.
Cause 3: Overfitting — Curve-Fitting to One Slice of History
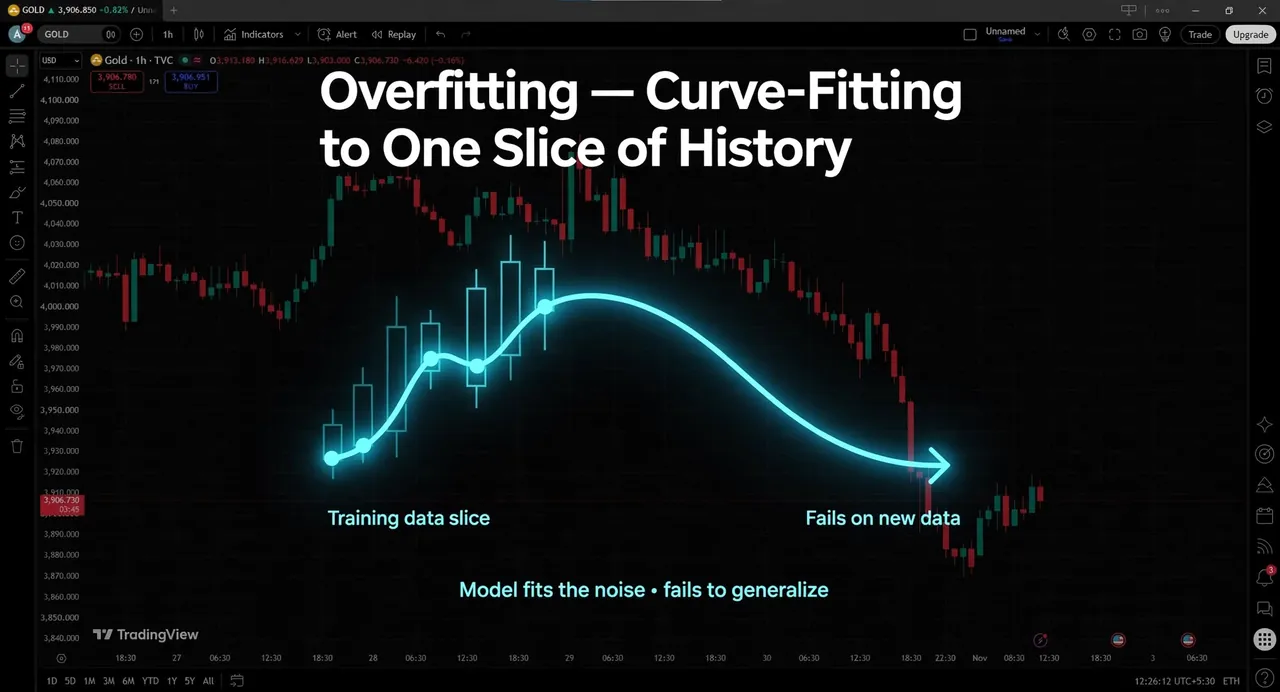
Even with a genuinely non-repainting signal and a look-ahead-free engine, a backtest can still be dishonest in a third, entirely different way: the strategy’s parameters were tuned until they fit one specific stretch of history almost perfectly, rather than capturing a genuine, repeatable market behavior.
Why More Parameters Make a “Great” Backtest Less Trustworthy
A sufficiently flexible strategy with enough adjustable inputs — entry threshold, stop distance, target, filter periods, time-of-day windows — can be tuned to fit any historical dataset, including pure noise. Academic work on backtest overfitting (notably research from Marcos López de Prado) shows that the more parameter combinations you test against the same data, the higher the probability that your “best” result is a statistical accident rather than a genuine edge.
A practical warning sign: a strategy with 500 historical trades but 8–10 tunable parameters may effectively have far fewer real degrees of freedom than trades. You have not found an edge — you have found the one combination that happened to fit the noise in this particular sample.
How to check: Prefer strategies that perform reasonably well across a range of nearby parameter values rather than one that only works at a single precise setting. A flat performance plateau across nearby parameters is a far stronger signal than a sharp peak at one exact number. Limit the number of free parameters you allow yourself to tune in the first place.
Out-of-Sample and Walk-Forward Testing — The Fix That Catches It
This is the step most retail backtests skip entirely, and it is the direct fix for overfitting: split your historical data into a training window (where you develop and tune the strategy) and a holdout window the strategy has never seen. If performance collapses on the holdout data, the strategy was fit to noise, not signal.
Walk-forward validation extends this further — instead of one train/test split, roll the window forward repeatedly: train on months 1–6, test on month 7; train on months 2–7, test on month 8; and so on. A strategy that holds up across multiple rolling out-of-sample windows has demonstrated something a single backtest cannot: that its edge is not tied to one historical accident. Reserve at least 20–30% of your data purely for out-of-sample testing, and treat any strategy that hasn’t been walk-forward validated as unproven, no matter how good the headline backtest number looks.
Survivorship and Selection Bias
Survivorship bias creeps in two ways. First, in the data itself — testing a strategy only on instruments that still exist today silently excludes everything that was delisted or failed, which flatters the average outcome (this matters more for equities and older crypto tokens than for major indices or FX). Second, and more subtly, in the idea generation process — if you scan 200 possible strategy variations and only backtest and report the 5 that looked promising, you have already curve-fit at the idea level before you ever touched a parameter. Be honest about how many variations you tried before landing on the one you’re backtesting now — if the answer is “dozens,” treat the result with proportionally more skepticism.
Regime Dependence — A Strategy Tuned for One Market Condition
A strategy backtested entirely across a strong trending run will look exceptional on trend-following logic and terrible the moment the market chops sideways or turns volatile. Most retail backtests cover a window that happens to be dominated by one regime — trending, ranging, high-volatility, low-volatility — without the trader realizing it, because the equity curve just looks like “up and to the right.” Deliberately test across multiple distinct market regimes — at minimum one clear trend period, one ranging period, and one high-volatility period (a crash or sharp reversal). A strategy that only performs in one regime isn’t broken, but it needs a regime filter or a reduced size outside its favorable conditions.
Cause 4: Slippage and Spread — The Silent Tax
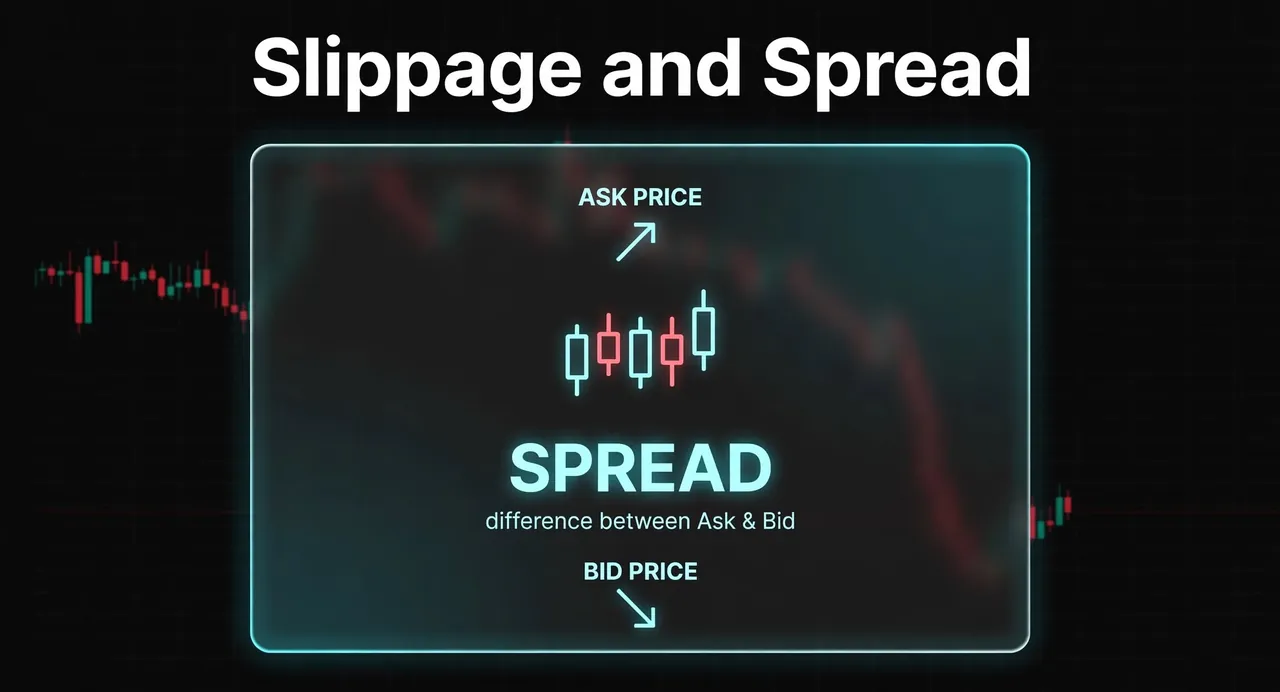
Even a perfectly non-repainting, look-ahead-free backtest will still diverge from live results if it assumes you can enter and exit at the exact quoted price with zero cost. In real markets, you cannot.
Where the Cost Actually Comes From
Spread. The difference between the bid and ask means every round-trip trade starts at a small loss before price moves at all. On a liquid major forex pair this might be a fraction of a pip; on a less liquid instrument or during low-liquidity hours, it can be several times larger.
Market impact and order-book depth. A market order does not fill at a single price — it walks up (or down) the order book, consuming liquidity at progressively worse prices as size increases. A backtest that assumes a fixed fill price ignores this entirely.
Volatility-driven slippage. During fast markets — news releases, session opens, low-liquidity windows — the price can move meaningfully between when your order is sent and when it is filled. This is the single biggest slippage source for breakout and momentum-style strategies, precisely the conditions those strategies are designed to trade.
Why It Disproportionately Hurts High-Frequency, Low-Edge Strategies
A strategy with a large average profit per trade can absorb a fixed slippage cost and remain profitable. A strategy that scalps small, frequent edges cannot. If your per-trade average edge is smaller than your realistic round-trip cost (spread plus typical slippage), the strategy is not marginally profitable — it is structurally unprofitable, and no amount of live-trading discipline fixes that. This is one of the most common reasons a backtest with hundreds of small winning trades turns into a live account that bleeds slowly.
How to Model It Correctly
- Backtest with a realistic cost assumption, not zero. Apply a fixed slippage estimate per trade (in points or basis points) that reflects the instrument’s typical spread plus a buffer for adverse fills, and re-run every backtest with that cost included before evaluating results.
- Separate cost assumptions by session. Slippage during a session open or a major news window is materially higher than during a quiet mid-session period. If your strategy trades around those windows, model that specifically rather than using a single blended average.
- Stress-test with a worse-than-expected slippage figure. If a strategy is only profitable under an optimistic slippage assumption, treat that as a warning sign, not a green light — real markets will occasionally deliver the worse case.
Cause 5: Execution Drift — The Gap Between “Should Have” and “Did”
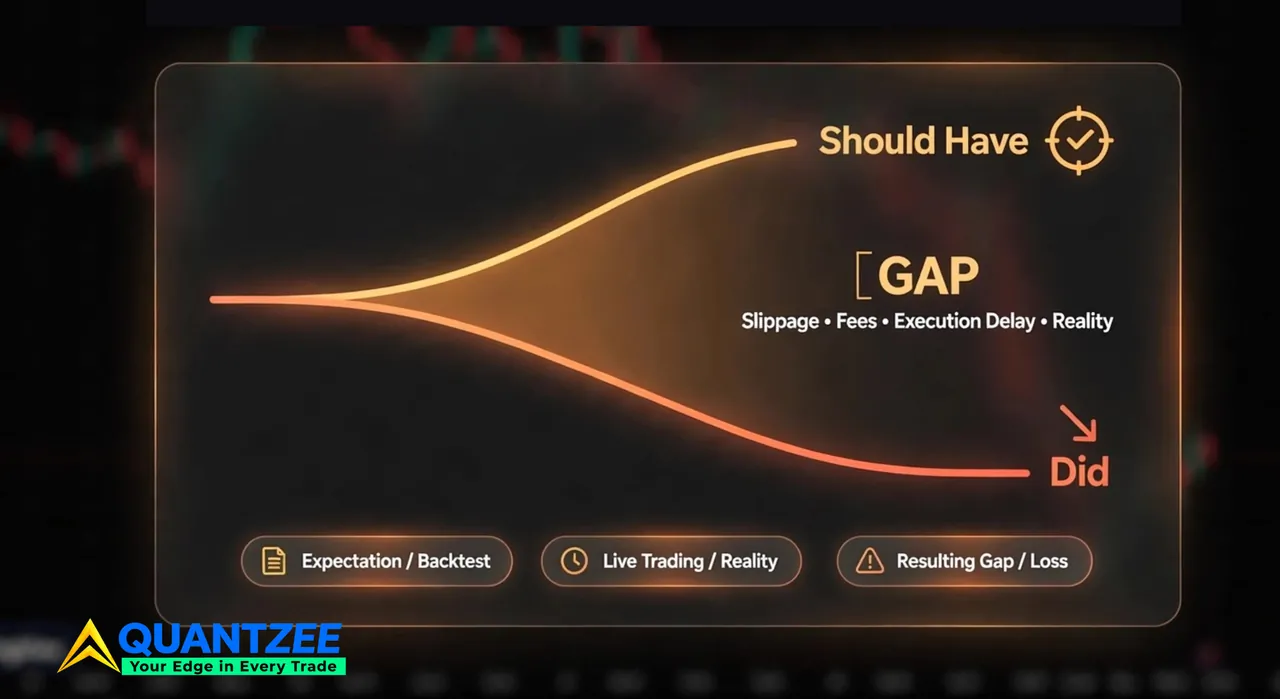
The final cause is the one that has nothing to do with the backtest’s math and everything to do with the mechanics of actually placing trades in real time.
What Execution Drift Includes
Order queueing and latency. Between the moment a signal fires and the moment your order reaches the exchange or broker, time passes — sometimes milliseconds, sometimes seconds depending on your setup. Price can move in that window.
Partial fills. Larger orders, or orders during thin liquidity, may only fill part of the intended size at the target price, with the remainder filling worse (or not at all).
Manual hesitation. For discretionary or semi-automated traders, the human element matters. A signal that a backtest assumes is acted on instantly is, in practice, often acted on a few seconds — or a few candles — later, after a moment of second-guessing. That delay alone can move an entry meaningfully worse than the backtested price.
Platform and connectivity issues. Missed alerts, delayed notifications, app connectivity drops, and broker order-routing quirks are all real-world friction that a spreadsheet-based backtest never encounters.
How to Reduce It
- Automate what you can. Alert-to-webhook automation removes the manual hesitation step entirely for traders willing to set it up, closing one of the largest gaps between signal and execution.
- Paper-trade in real time before going live. Not a backtest — a genuine forward test where you watch signals fire in real time on a live feed and log exactly when and at what price you could have entered, without hindsight. This surfaces execution drift that no historical backtest can.
- Track your actual fills against the signal price. Keep a simple log: signal price vs. actual fill price, for every trade, for at least 30–50 trades. If the average gap is consistently in one direction, that is your execution drift, quantified.
If you are automating entries through TradingView alerts into a broker or bot, the latency chain has extra links: TradingView must detect the bar close, fire the alert, deliver the webhook, and your receiving endpoint must parse and place the order — each hop adds milliseconds that a backtest assumes away entirely. On fast-moving instruments during high-volatility windows, that chain of delays is exactly where a theoretically profitable scalping strategy quietly turns into a breakeven or losing one. Testing the full alert-to-fill pipeline on a small live order, not just the strategy logic in isolation, is the only way to measure this gap directly.
Why Simulated Equity Curves Look Smoother Than Real Ones
There is a structural reason a backtest’s equity curve is almost always visually smoother than a live one, beyond any single bias listed above: a backtest processes every historical bar with the same calm, unemotional consistency, while live trading adds two things no simulation can fully replicate — psychology and irregular information flow. A backtest never hesitates before a signal, never second-guesses a stop-loss, and never sees a news headline mid-trade that makes the human on the other end of the screen close early or add size impulsively. Even a mechanically identical strategy, executed by a human rather than code, produces a noisier equity curve purely from inconsistent execution discipline. This is a reason to expect some divergence even from a backtest that has passed every check on this page, and to size positions conservatively until the live equity curve has enough history of its own to judge against.
The Practical Checklist: Closing the Gap Before You Trade Real Size
Put together, here is the sequence that catches all five causes before capital is at risk:
- Confirm the indicator or signal source is genuinely non-repainting using the bar-replay test described above. Do this before anything else — if the underlying signal is repainting, every subsequent step is built on a false foundation.
- Audit the backtest engine for look-ahead access. Confirm entries use only prior closed-bar data, and that any parameter tuning was validated on an out-of-sample slice that was never touched during optimization.
- Check for overfitting. Limit tunable parameters, confirm performance holds across a range of nearby parameter values (not one sharp peak), and reserve 20–30% of history purely for out-of-sample testing.
- Walk-forward validate across at least 3 rolling windows, not a single train/test split. A strategy that only performs well on one specific historical split is far more likely to be curve-fit than one that holds up across several independent windows.
- Cover multiple market regimes in the test window — at minimum one trend period, one ranging period, and one high-volatility period — so the backtest isn’t silently overfit to a single market condition.
- Re-run the backtest with realistic slippage and spread costs applied, not a zero-cost assumption. If the strategy’s edge disappears under a realistic cost model, it was never a tradeable edge.
- Forward-test (paper trade) in real time for a meaningful sample size — at least 100 trades, ideally 200+ — before committing capital. This is the only stage that actually captures execution drift, because it is the only stage happening in real time rather than in review.
- Compare live results against the backtest continuously, not just once. Track a rolling comparison of live equity curve shape against the backtested expectation. A widening, persistent gap — beyond what normal statistical variance would explain — is the signal to stop and re-diagnose, not to keep trading through it.
Treat the checklist as a gate, not a formality: if a strategy fails step 1 (repainting) or step 4 (walk-forward), stop there — fixing costs or regime coverage on a strategy built on a repainting signal is polishing a number that was never real to begin with.
None of these steps guarantee that live performance will match a backtest exactly — markets change, and no amount of process eliminates that. But they eliminate the avoidable sources of the gap, which in practice account for the overwhelming majority of “my backtest doesn’t match live trading” experiences.
How This Applies to Indicator-Based Trading
If you trade off an indicator rather than a full mechanical strategy, the same gaps apply in a slightly different form. A repainting indicator inflates the apparent win rate of every setup built around it — this is the single biggest reason a discretionary trader’s “it worked great on the chart” experience does not survive contact with live trading. Before trusting any signal tool, confirm it holds its position after bar close, and understand whether the vendor validates it against forward (not just historical) data. We cover the exact five-minute test for catching a repainting indicator in our guide to testing any TradingView indicator for repainting.
At Quantzee, every indicator we publish — from MACD Pro+ to SuperTrend Pro+ — is built to confirm signals only on bar close and is checked against live forward data before release, specifically to close the gap this article describes. You can see the reasoning behind that standard in our guide on non-repainting TradingView indicators, and browse the full validated suite on the Quantzee indicators page.
Summary: The Gap Is Diagnosable, Not Mysterious
A backtest that doesn’t match live trading is not a reason to abandon backtesting — it’s a signal that one or more of five specific, checkable problems exists somewhere in the process: a repainting signal source, look-ahead bias in the backtest engine, overfitting/curve-fitting to one historical window, unmodeled slippage and spread cost, or execution drift between signal and fill. Every one of these has a concrete diagnostic test and a concrete fix.
The core takeaways:
- Repainting indicators redraw historical signals with future information — always verify non-repainting behavior with a bar-replay test before trusting a backtest built on top of it.
- Look-ahead bias hides in backtest engine mechanics, not just indicator math — audit entry/exit timing and separate your optimization data from your validation data.
- Overfitting and regime dependence silently inflate backtest results — walk-forward validation across multiple rolling windows, spanning multiple market regimes, is the fix.
- Slippage and spread are not rounding errors — they can turn a backtested edge into a live loss, especially for high-frequency, low-per-trade-edge strategies.
- Execution drift — latency, partial fills, manual hesitation — is the one gap source a historical backtest structurally cannot capture, which is why real-time forward testing is not optional.
- Closing the gap is a repeatable process, not a one-time fix: verify the signal, audit the engine, check for overfitting, model realistic costs, cover multiple regimes, forward-test in real time, and validate with walk-forward windows before scaling capital.
Disclaimer: This article is educational content published for informational purposes only. It is not investment advice, a trading recommendation, or a solicitation to buy or sell any financial instrument. Trading involves substantial risk of loss and is not suitable for all investors. Backtested and forward-tested performance, whether hypothetical or real, does not guarantee future results. Quantzee’s indicators are analytical software tools — they are not investment advisory services. Please do your own research and consult a licensed financial advisor before making any trading decisions.