Most comparisons of backtesting software ask which tool has the nicer interface, the bigger universe, or the lowest monthly price. That question is answerable in an afternoon. It is also the wrong one. The question that actually decides whether an equity curve means anything is narrower: can you see, and control, the five assumptions the engine makes about fill price, cost, data, universe, and timing? Get those five right and a plain interface is a minor annoyance. Get them wrong and a polished dashboard is reporting a number that never happened, a problem that only gets sharper once you add a futures-specific set of rollover and session rules on top of the original five.
We read through three of the most-cited roundups of backtesting software — from LuxAlgo, TradeZella, and TrendSpider — looking for how each handles those five points. The short version: all three are useful for narrowing a shortlist. All three skip the same ground. None compares how the tools model transaction cost in any depth. None addresses survivorship bias in the symbol universe. None shows what the same strategy returns when it's run on two different platforms with the same data. LuxAlgo states plainly that its piece is an editorial assessment of documented capabilities, not an independently run benchmark. That's honest, and it's also the tell for why this comparison takes a different shape.
The five assumptions, named up front
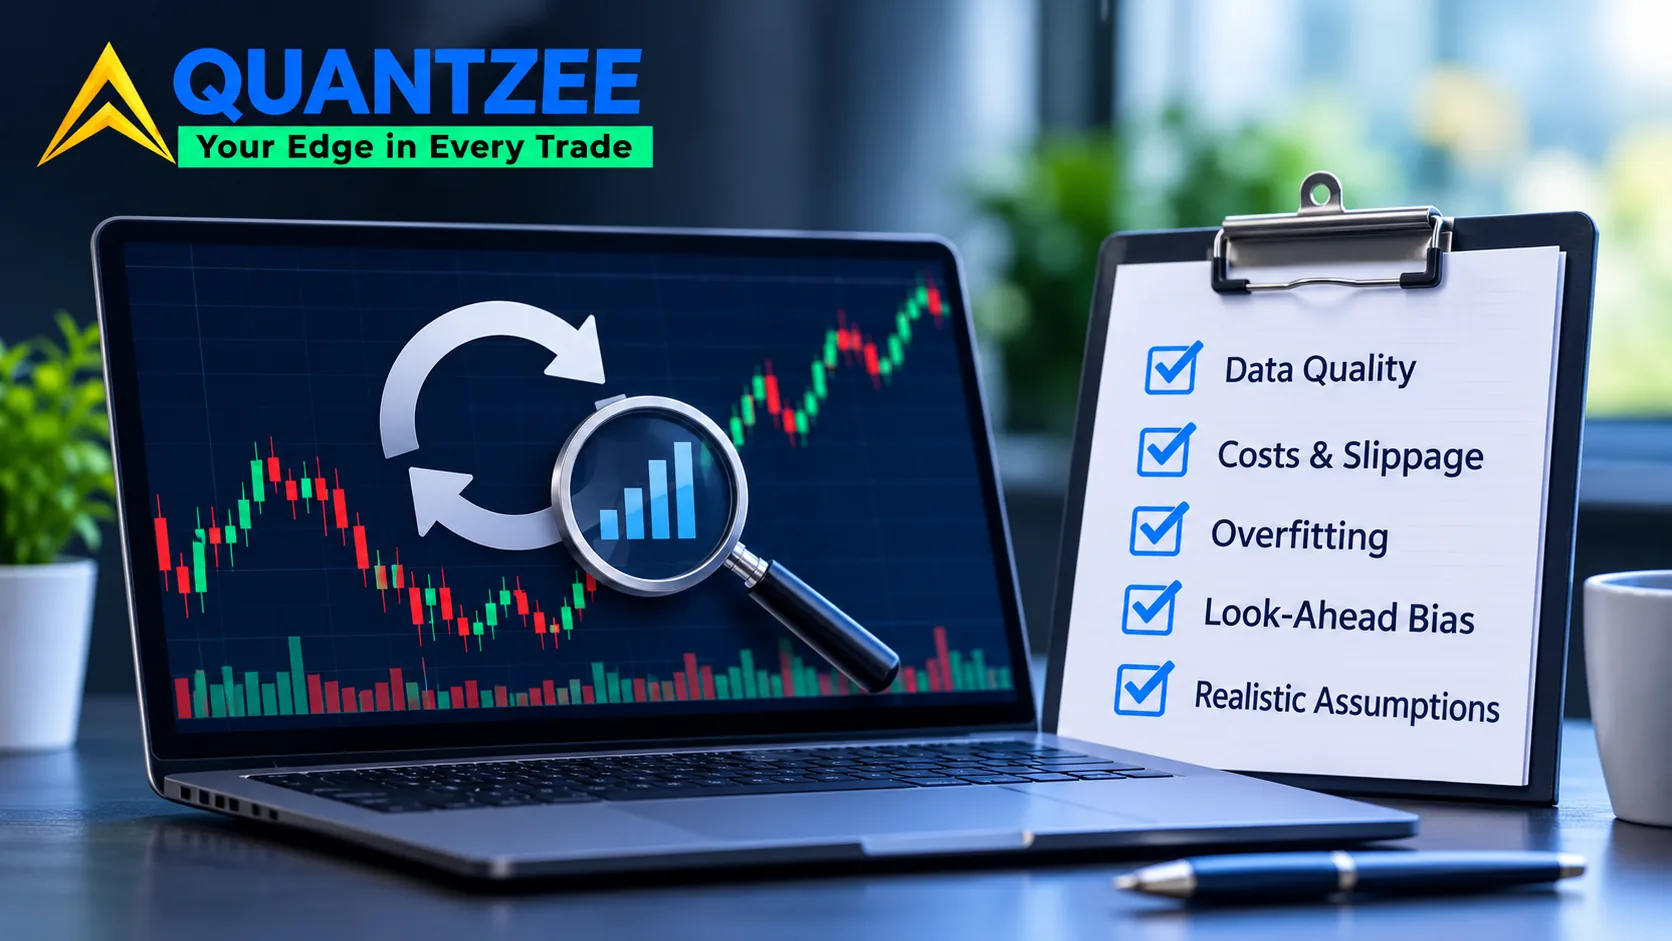
Every backtesting software package — from a free TradingView strategy tester to an institutional-grade platform — is making five decisions whether or not it tells you so. According to the SEC's investor guidance on hypothetical performance, backtested results are after-the-fact constructions by definition. The only honest framing is which assumptions you can see and which ones stay hidden. Here they are, roughly in the order they tend to matter:
- Fill price — does the engine fill at the signal bar's close, the next bar's open, or a resting limit price inside the bar?
- Cost model granularity — fixed per trade, flat percentage, per-share tiered, spread simulation, or size-dependent slippage?
- Data resolution and provenance — what timeframe feeds the test, and which vendor supplied the candles?
- Universe construction — does the symbol list include names that have since delisted, merged, or gone bankrupt?
- Look-ahead safety — how is the boundary handled between the bar that generates a signal and the bar that executes on it?
Read a vendor's documentation with these five questions in hand before reading its marketing page. The marketing page tells you what the tool does well. The documentation, if one exists, tells you what the tool actually computes. Secondary keyword searches like best backtesting software or backtesting softwares usually surface the marketing page first and the documentation several clicks later, if at all.
Fill price is where most of the fake profit lives
We've tracked this one closely because it's the single biggest driver of backtest-to-live slippage we've seen across our own backtest vs live trading mismatch work. A tool that fills every trade at the exact close of the signal bar is quietly assuming zero latency and zero market impact. No live order gets to make that assumption. Move the same setting to "next bar open," and the strategy's win rate and average trade can shift sharply. We've seen average trade move by 20% to 40% on the same rule set, purely from this one toggle, with no other input changed.
In our experience building and stress-testing option-selling systems, a strategy that looks strong on close-fills and collapses on next-open fills is not a strategy with a timing edge. It's a strategy whose entire edge was the assumption, not the logic. Before trusting a result from any backtesting software, find the fill-price setting, change it, and re-run. If the output moves by double digits, you've learned more about the tool than about the strategy.
Cost model granularity: the comparison axis the roundups skip
A flat $1-per-trade commission and a tiered, size-dependent slippage model that widens as position size grows are not two flavors of the same feature. They're two different capabilities. A platform offering only the first cannot represent an active trading style with any fidelity. We counted five distinct cost-modeling tiers across the tools we reviewed:
- Fixed per-trade fee — the crudest model, acceptable for a buy-and-hold test, wrong for anything with real turnover.
- Flat percentage of notional — better, but it still ignores that small orders and large orders don't face the same market impact.
- Per-share or per-contract tiered pricing — this matches how most brokers actually bill.
- Spread simulation — models the bid-ask spread you'd actually cross, not just a commission line item.
- Size-dependent slippage — the only model that captures what happens when an order is large relative to the book.
TradeZella's roundup runs to roughly 6,500 words across ten platforms, according to its July 2026 update, but it doesn't break cost modeling into tiers at all — cost gets one line item, not a comparison axis. TrendSpider's piece, built around no-code strategy building, treats commission and slippage generically too, with no mention of futures rollover or session-based fee differences. If a strategy trades more than a handful of times a month, ask which of these five tiers the tool actually implements before asking anything about its interface.
The gap between tier one and tier five is not academic. A strategy that trades 40 times a month, tested with a flat $1 commission, can show a very different annual return than the same rule set tested with size-dependent slippage that widens as the position grows past a few hundred shares or a handful of option contracts. We've seen cases where the gap between the two cost models erased more than half of a backtest's reported edge, and the strategy's logic never changed at all — only the cost assumption did. If a platform's pricing page doesn't mention which of the five tiers it supports, that's usually because it only supports the first one or two, and the sales team would rather you ask the question yourself than read it off the page.
Universe construction and survivorship bias
A backtest run only on symbols still trading today is, by construction, measuring a selected sample. It has already excluded every company that went bankrupt, got delisted, or merged out of existence during the test window. Academic work on survivorship bias, including research distributed through the National Bureau of Economic Research, has found this effect alone can inflate reported long-horizon equity returns by several percentage points a year. Most retail backtesting software does this silently, because building and maintaining a point-in-time universe — one that includes names that later disappeared — is expensive data infrastructure that most vendors haven't built.
None of the three roundups we read raises this at all. That's not a knock on any single platform. It's a blind spot in how backtesting software gets marketed, because "our universe has 8,000 symbols" sounds like a feature regardless of whether those 8,000 are the symbols that existed on day one of the test or the symbols that happen to still exist today, three or five years later. Ask the vendor directly: is the universe point-in-time, or is it today's list applied retroactively? Most sales pages won't volunteer the answer. Most support teams can, if you ask the specific question.
This matters more for strategies built on small-cap or sector-rotation universes than for a single-index strategy on NIFTY or the S&P 500, where the index membership itself is the universe and survivorship is largely handled by the index provider. But it matters a great deal for any screen-based or scan-based strategy that pulls from a broad symbol list, or any attempt to spread one system across several markets, because that's exactly the kind of universe where delisted names get quietly dropped from a vendor's current database. A test that ran across 2018 through 2026 using today's symbol list has, in effect, replayed eight years of market history with the benefit of knowing in advance which companies survived it.
Look-ahead safety: the boundary between signal and execution
This is the hardest of the five to catch by eye, because a look-ahead bug produces results that look completely plausible — just too good. The failure happens at the boundary between the bar that generates a signal and the bar the engine lets you trade on. Two mistakes account for almost every case we've seen over several hundred strategy reviews.
First, using a bar's own close to both compute an indicator and fill the trade on that same bar. The engine is handing over information — the bar's final close — before that information actually existed in real time. Second, applying a repainting indicator without shifting its signal by a full bar, so the backtest sees the final, settled version of a value that was still changing as the bar printed. Either mistake can turn a losing idea into a winning backtest. Neither shows up unless you deliberately shift every signal forward by one bar and re-run to see whether the edge survives.
A third variant shows up specifically in multi-timeframe strategies: pulling a higher-timeframe value — a daily pivot, a weekly high — into a lower-timeframe signal before that higher-timeframe bar has actually closed. The daily candle isn't final until the day ends, so a 15-minute strategy that references "today's high" at 11 a.m. is referencing a number that will keep changing for another five hours. Backtesting software that resamples higher timeframes incorrectly will quietly use the finished value throughout the day, which is exactly the kind of error that never shows up unless someone goes looking for it on purpose.
Reconciliation: the only real test of a backtesting tool
Everything above is a documentation exercise. You're reading what a vendor says the engine does. The only way to verify it is to run one simple, fully specified rule on two different platforms with identical data and identical cost settings, then measure the gap between the two outputs. That gap is your measurement error. It's the number you live with no matter which tool you eventually choose.
We've published our own test setup for this kind of cross-check in our backtest-versus-live comparison, and the pattern holds generally: a strategy that reconciles to within a few percent across two engines on a simple rule is telling you something real about the market. A strategy whose result swings wildly depending on which engine ran it is telling you something about the engines, not the market. To be clear about what we are and aren't claiming: we have not run a formal reconciliation across LuxAlgo's, TradeZella's, and TrendSpider's platforms specifically, and neither had any of the three roundups we read. The claim that holds up is narrower — whichever tool exposes its assumptions clearly enough for you to run this reconciliation yourself is the one worth paying for.
Why vendor roundups rank themselves first — and how to read one anyway
LuxAlgo's comparison, at roughly 4,500 words covering eight platforms published in July 2025 and reviewed again in October 2026, puts LuxAlgo first. TradeZella's piece, at roughly 6,500 words covering ten platforms and updated in July 2026, puts TradeZella first with close to double the word count of any competitor entry and reports no stated disadvantage of its own product anywhere in the piece. TrendSpider's 2026 roundup leans on criteria built around no-code strategy building and deployment, which happens to describe TrendSpider closely. None of this makes the three pieces useless. Each is a reasonable starting shortlist, and reading three independently-authored roundups against each other is a legitimate way to triangulate a feature set.
The tell to look for is a stated disadvantage. A comparison that names a genuine weakness in its own product — a missing feature, a pricing tier that's expensive for small accounts, a steep learning curve — is doing real comparative work. A roundup that recommends its own tool and lists zero drawbacks for it, while finding several gaps in everyone else's, has told you about its incentives more than about the market. Read for the absence of a disadvantage before reading the ranking itself.
A buyer's checklist for evaluating backtesting software
A ranked list goes stale the moment a vendor ships a new release. A set of questions aimed at the documentation doesn't, so here's what we'd actually ask before signing up for any backtesting software, Quantzee included.
Start with fills: does the documentation state, in writing, whether trades fill at signal-bar close, next-bar open, or a resting limit? Move to cost: does the model go past a flat commission to size-dependent slippage, and can you set it per instrument rather than account-wide? Check the universe: is the symbol list point-in-time, including names that later delisted, or is it today's list run backward across five or ten years of history? Ask about timing: how does the vendor prevent a signal from using data that wasn't yet available when the bar closed? And test the one question a feature table can't answer — will the vendor's own support team walk you through reconciling one simple rule against a second platform within a day or two, or do they treat the request as unusual?
That last question is worth testing before you buy, not after. A platform confident in its own assumptions will usually help you verify them without friction. One that gets defensive about a basic reconciliation request is telling you something too.
A quick glossary for reading any backtest report
Vendor documentation throws around terms that don't always mean the same thing from one platform to the next. Two are worth pinning down before you read another feature comparison.
Our own backtesting glossary entry defines the term the way we use it across every piece we publish: a historical simulation of a rule set against past price data, under a stated set of fill, cost, and data assumptions. That last clause is the part most glossaries leave out, and it's the part that actually matters once you're comparing two tools instead of reading about one.
The second term worth knowing cold is overfitting. Our overfitting glossary entry covers the mechanism: a rule set tuned against one historical sample until it fits that sample's noise, not just its signal, so it performs well on the data it was built on and poorly on everything after. Backtesting software can't stop you from overfitting — that's a process failure, not a tool failure — but a platform that makes it trivial to re-run hundreds of parameter combinations against the same fixed window makes overfitting easier to do by accident. If a tool advertises one-click optimization across a wide parameter grid, treat that as a feature that needs a second, out-of-sample window before you trust anything it produces.
Stress-test the strategy, not just the backtest settings
Everything in this piece so far is about whether the software is telling you the truth about one historical run. A separate, harder question is whether that one run would hold up across different market conditions — a higher-volatility stretch, a trending month instead of a ranging one, a period with wider bid-ask spreads. Our stress-testing checklist walks through the specific conditions worth testing against, separate from the fill-price and cost-model questions covered here.
The two checks are complementary, not redundant. A strategy can pass every assumption check in this piece — honest fills, realistic costs, a point-in-time universe, no look-ahead — and still fail because it only works in the one volatility regime the historical window happened to cover. Run both passes before any strategy, on any platform, gets real capital behind it.
Frequently Asked Questions
If TradingView is one of the tools on your shortlist, its fill model has its own quirks (it guesses the order of price moves inside a bar unless you have a plan with Bar Magnifier). We list them in our TradingView backtesting guide.
What this means for how you test your own strategies
None of this is an argument against using backtesting software. It's an argument for treating the output as conditional on five settings, not as a fact. A win rate of 58% on a 1,200-trade sample means one thing if fills happen at next-bar open with size-dependent slippage. It means something different if that same number came from close-fills with a flat commission. Both numbers can come out of the same engine, on the same data, from the same rule — the only difference is which assumptions were turned on.
That's the reason a strategy deserves a short reconciliation pass before capital goes anywhere near it. Change the fill setting. Change the cost model. Shift the signal by a bar. Watch how much the result moves each time you flip one switch. A strategy that holds up across all three checks has earned a smaller amount of skepticism. One that falls apart on the first change was never really tested — it was described.
In practice this takes less time than most traders expect. A single rule set, re-run four or five times with one assumption changed each pass, usually takes under an hour once the platform's settings are familiar. Compare that hour against the weeks or months a strategy might run live before a trader notices the backtest never matched reality. The reconciliation pass is cheap. The alternative — discovering the gap with real capital on the table — is not.
Paper trade first regardless of which checks a strategy passes. A clean backtest, however honestly built, is a historical measurement on a fixed sample, not a forecast. It describes what a rule set would have done under one specific set of past conditions and assumptions, nothing more. Quantzee's own tools are built to analyze that history, not to advise on what to do with it, and the five assumptions in this piece are the lens we'd point at any platform's output, including our own, before trusting a single number from it.